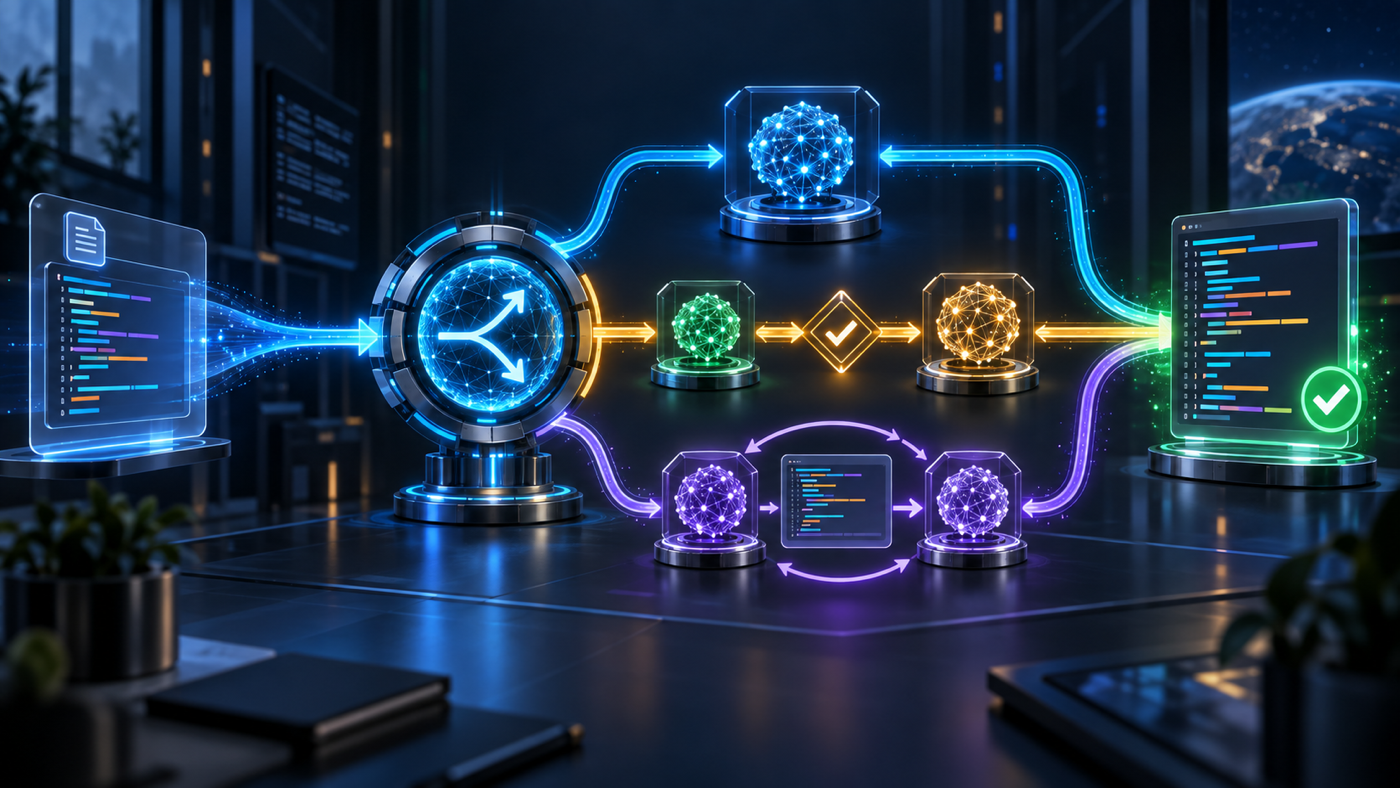
GitHub is testing a different architecture for coding agents: instead of assigning every task to one model, Project HydraFusion chooses an execution strategy at runtime.
For each request, HydraFusion can:
- send the task directly to one model;
- let an efficient model attempt it, then escalate if it fails a quality gate;
- have one model draft the solution while a model from another family critiques it before revision.
The research preview is available through /experimental in GitHub Copilot CLI. On September 14, GitHub also introduced efficiency, balance, and intelligence preferences for Copilot’s broader automatic model selection, allowing developers to influence how it weighs cost, quality, and response time.
GitHub reports that HydraFusion’s controlled offline evaluations delivered between 36% and 67% lower estimated cost than Claude Opus 5, while benchmark quality ranged from 1.5 percentage points lower to 4.9 points higher. These are vendor-reported preview results, not independent production measurements.
Why it matters
The coding-agent contest is moving beyond “which model is best?” toward “which combination of models and review steps best fits this task?”
This extends the agent-harness direction behind OpenAI’s Agents API: the competitive advantage increasingly comes from routing, tools, evaluation, and execution policy around the model—not only from the model itself.
For builders, HydraFusion points to an important pattern: use inexpensive inference for straightforward work, reserve frontier models for difficult cases, and introduce independent critique when review is more valuable than another unaided attempt. If the approach holds up in real projects, orchestration could improve agent economics without forcing developers to manage every model decision manually.