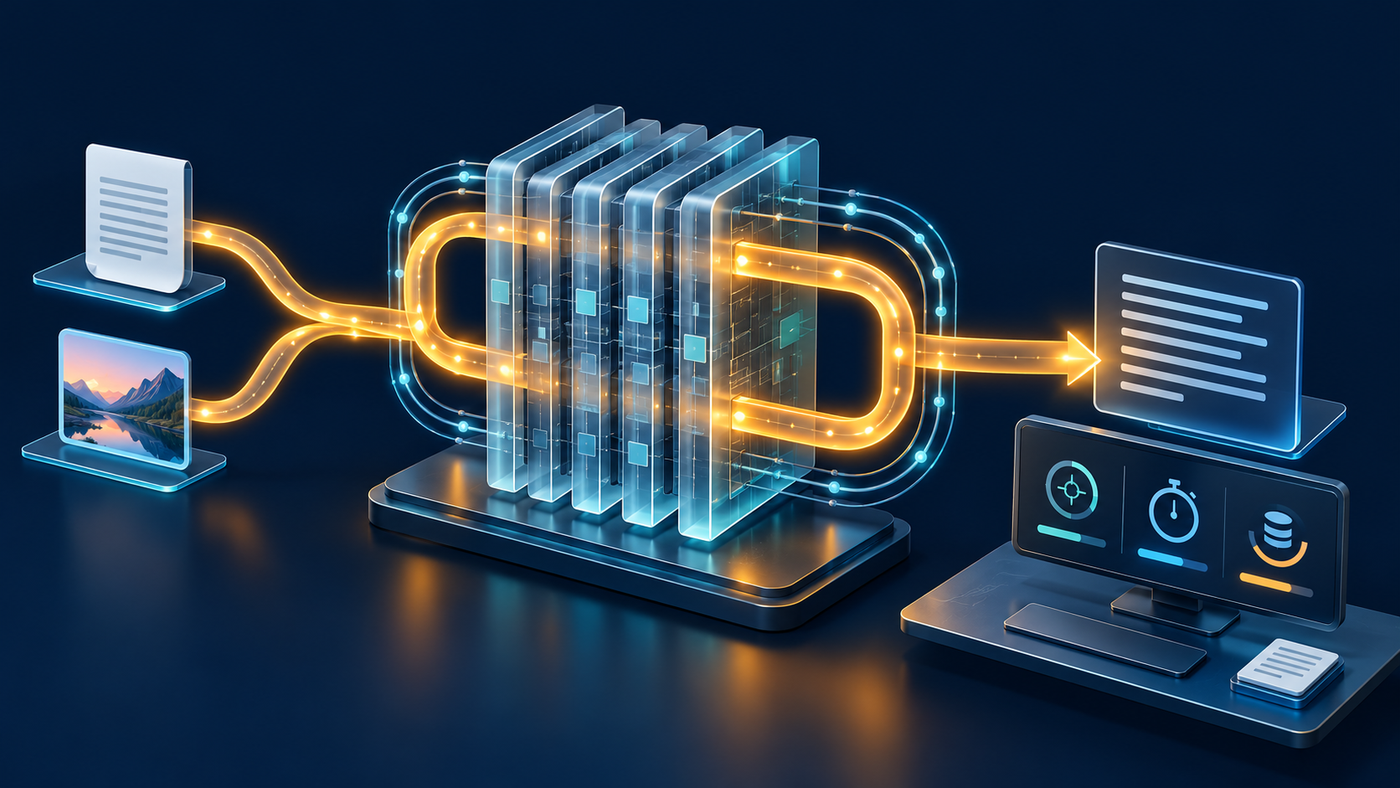
SenseNova released SenseNova-Loop-9B-Preview on October 30, adding an Apache-2.0 open-weight model for document understanding, coding and tool-connected workflows. It accepts text and images, generates text, and was trained on sequences reaching 262,144 tokens.
A deeper processing path through shared weights
Its distinctive feature is weight reuse. A block of 24 decoder layers runs twice, producing 56 layer computations while storing only 32 distinct layers. The second pass takes the first pass’s output through the same shared block.
That creates a deeper execution path without storing a second copy of the repeated weights. It does not make the extra computation free, nor does the layer count alone establish better answers or faster inference.
Why it matters for builders
The release offers developers three concrete reasons to experiment:
- Multimodal input: combine images and instructions in document-understanding and tool-connected workflows.
- Self-hosting flexibility: downloadable, permissively licensed weights support controlled evaluation.
- A different scaling trade-off: reuse model layers rather than continually adding separate sets of weights.
A preview to evaluate, not a finished agent
The technical report is still pending, deployment uses a custom model implementation, and actual speed depends on hardware, workload and serving configuration. The release alone does not establish a production-quality advantage over existing models.
For SunMarc App Labs, a useful first test would be screenshot-and-instruction tasks from our own apps, comparing accuracy, latency and serving cost before considering integration. This is a proposed evaluation, not an announced deployment.
Our coverage of Liquid AI’s LFM3 family for local multimodal applications explores another approach to matching models to bounded app tasks. Different architectures still need to be measured on the work a product actually requires.